Sep 22, 2026

How to Search a Website for Keywords in 5 Steps
DraftSEO Team
Google's site: operator only shows pages it has indexed — which means it can miss noindexed pages, orphaned URLs, and staging content entirely. That gap matters if you're trying to figure out how to search a website for keywords before publishing something new. Most people stop at "did this keyword appear somewhere," when the real question is what to do once you know where it lives.
This matters most during content audits, before launching a new page that might cannibalize an old one, or when a client asks why two blog posts are competing for the same search term. Getting the method right the first time saves you from chasing phantom results or misreading rankings data as keyword placement data.
Step 1: Check One Page at a Time With Ctrl+F
Ctrl+F (or Cmd+F on a Mac) opens your browser's find function, and it searches only the page you have open — not the whole website. This is the single most common mix-up in keyword audits: someone assumes hitting Ctrl+F on the homepage will surface every instance of a phrase site-wide, and it won't.
Use it when you already know which URL you're checking and just need to confirm keyword placement — in the title tag, first 100 words, headers, or alt text. It's fast, free, and built into every browser, which makes it a good gut-check tool once you've narrowed things down using site-wide methods.
Don't rely on it as your primary discovery tool. If you're auditing a site with more than a handful of pages, Ctrl+F becomes a page-by-page slog with no way to aggregate results. Save it for verification, not discovery.
Step 2: Run Google's site: Search Operator for a Quick Scan
Typing site:yourdomain.com "your keyword phrase" into Google shows which indexed pages contain that phrase, based on Google's own index — not a live scan of your site's code. It's the fastest way to get a rough answer, and it takes about 10 seconds.
The catch: this only reflects what Google has crawled and chosen to index. Pages marked noindex, blocked by robots.txt, buried in a slow-loading JavaScript framework, or simply not yet crawled won't show up, even if the keyword is sitting right there in the HTML. I've seen agencies conclude a keyword was "safe to use" on a new page, only to find out later that three other pages had it too — they just hadn't been indexed at the time of the check.
Treat site: search as a starting point, not a verdict. Cross-check anything important against a full crawl, especially on larger e-commerce catalogs where product variants and filtered URLs often sit outside the index.
Step 3: Crawl the Whole Site With Screaming Frog or Ahrefs
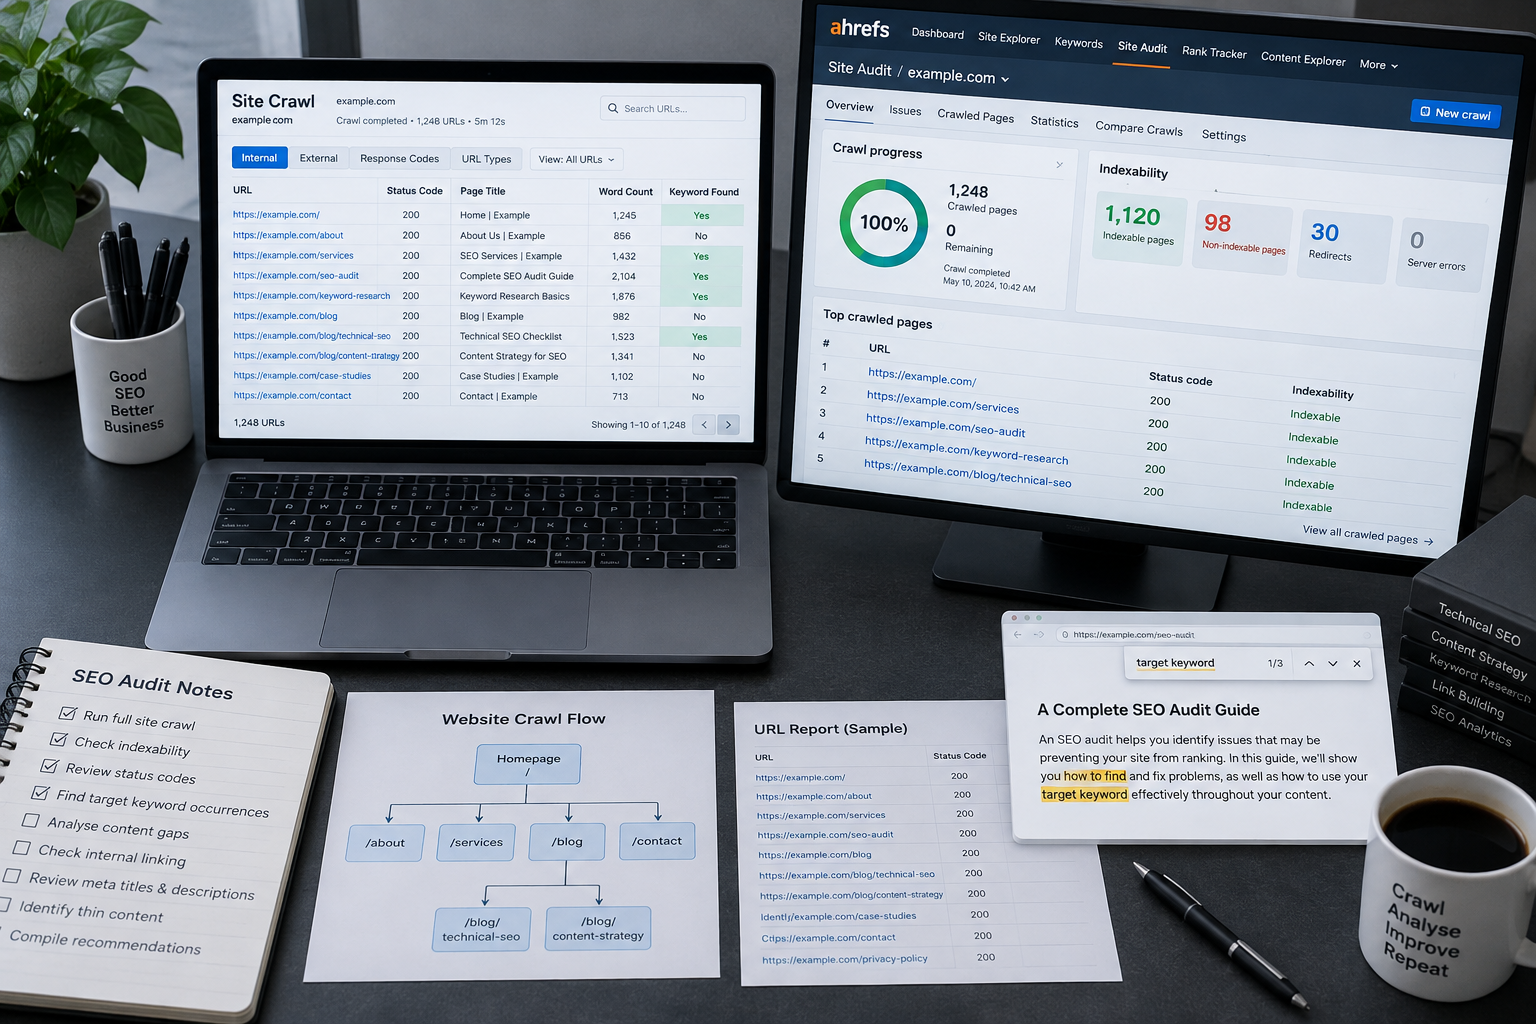
This is where technical SEOs get their real answer, and it's the step that separates a surface-level check from an actual audit. A crawler reads your site's raw HTML — every indexed and unindexed page — and lets you search for exact keyword matches across titles, headers, body copy, and meta descriptions in one pass.
Screaming Frog SEO Spider
Screaming Frog's free tier crawls up to 500 URLs, which covers most small-to-midsize business sites. Point it at your domain, let it crawl, then use the built-in "Custom Search" filter (under Configuration) to search for your target phrase across every URL at once. Export the results to a spreadsheet and you've got a full keyword-location map in minutes.
Ahrefs Site Explorer
Ahrefs works differently — it's built around backlink and ranking data rather than raw HTML search, but its Site Audit and Content Explorer tools let you filter pages by keyword in title tags, meta descriptions, and organic ranking terms. It's a good complement to Screaming Frog when you want to layer search volume and ranking position on top of raw placement data.
Pulling Data From the XML Sitemap
Feed your XML sitemap directly into a crawler instead of crawling the whole domain organically — this catches pages that exist but have weak internal linking, which a standard crawl sometimes skips. It's a quick way to confirm your sitemap and your actual indexed footprint aren't drifting apart.
Step 4: Separate Keyword Search From Ranking Data in Search Console
Google Search Console tells you which queries a page ranks for and how often it's clicked — it does not tell you whether a keyword phrase physically appears in that page's content. These are two different datasets, and confusing them is a common audit mistake.
A page can rank for "best running shoes for flat feet" without that exact phrase appearing anywhere in the copy, thanks to semantic matching and related terms. Conversely, a page can contain a keyword five times and still get zero impressions for it. Search Console shows performance, not placement — you need a crawl tool for placement, and Search Console for the ranking result that placement produces.
Use them together: crawl first to find every page containing (or missing) a target phrase, then check Search Console's Performance report filtered by that query to see which of those pages Google actually rewards. If your top-ranking page for a term isn't the one with the strongest, most relevant content, that's a signal worth investigating.
Step 5: Turn Keyword Locations Into a Cannibalization and Gap Report
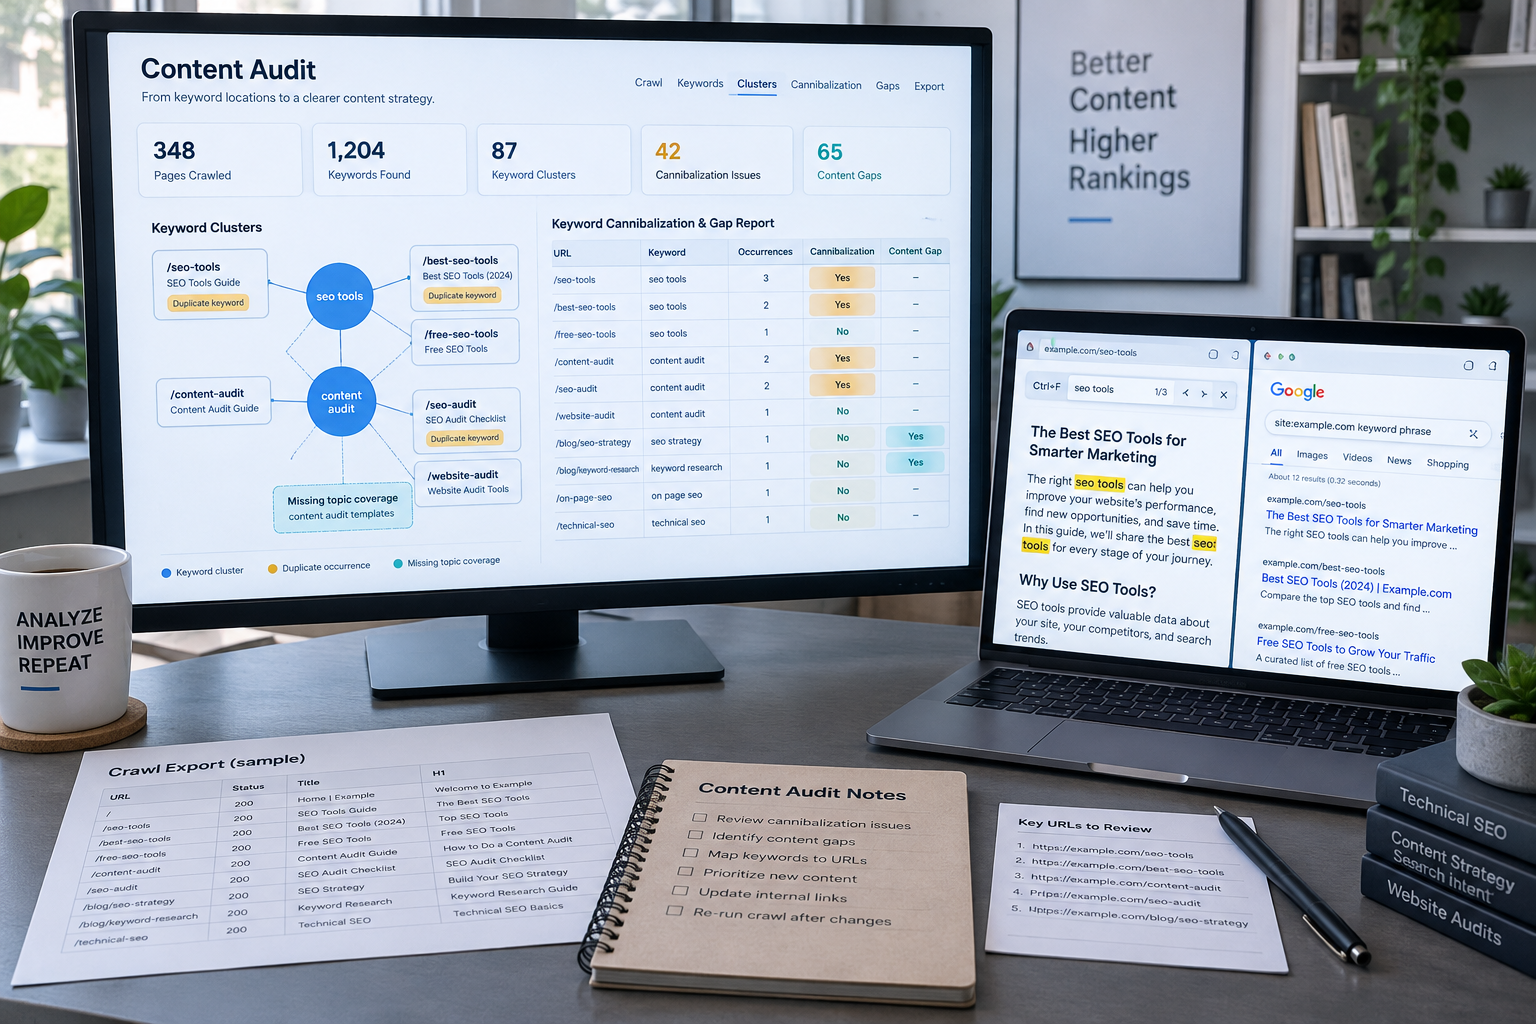
Finding where a keyword lives is only useful if you act on it. Once you have your crawl export, sort by keyword and page, then flag any term appearing in the title tag or H1 of more than one URL — that's your cannibalization list.
- Export all pages containing your target keyword from Screaming Frog or Ahrefs.
- Cross-reference those URLs against Search Console impressions for the same query.
- Flag any keyword with two or more pages ranking in the same 10-position range.
- Check each flagged pair for thin or duplicate content — often one page can absorb the other.
- Merge, redirect, or differentiate the weaker page's targeting.
- Log remaining keywords with zero page coverage as your content gap list.
- Prioritize gap keywords by search volume before writing new pages.
This is the step most guides skip entirely, and it's where the actual SEO value sits. A keyword search that stops at "yes, it's on page X" leaves cannibalization and duplicate content sitting unresolved. Platforms like draftseo.ai are built around this exact follow-through — using a content gap list generated from your crawl data to automatically produce new pages targeting the terms you're actually missing, instead of duplicating what's already ranking.
The table below shows how the main tools split by scope and cost, which helps when deciding what to run first.
| Tool | Scope | Shows Ranking Data | Typical Cost |
|---|---|---|---|
| Ctrl+F | Single open page | No | Free |
| Google site: operator | Indexed pages only | No | Free |
| Screaming Frog | Full site crawl (free up to 500 URLs) | No | Free / $259 per year (paid) |
| Ahrefs Site Explorer | Full site + backlink and SERP data | Yes | Starts around $129/month |
| Google Search Console | Indexed pages, query-level | Yes | Free |
Frequently Asked Questions
Does my WordPress site's built-in search bar work for a keyword audit?
No, not reliably. The default WordPress search bar searches published post and page titles and body content, but it ignores meta descriptions, alt text, and often custom fields, so it undercounts real keyword placement. A plugin like SearchWP or Relevanssi extends that scope, but for a full audit you still need a proper crawler.
Can I check keyword density with these same tools?
Yes — Screaming Frog's Custom Search combined with word count data lets you calculate rough keyword density per page, though modern SEO cares far less about density than it did a decade ago. Focus more on placement in titles, H1s, and the first 100 words than on hitting a specific percentage.
What's the fastest way to find duplicate content across many pages?
Run a full site crawl and export title tags, H1s, and meta descriptions to a spreadsheet, then sort alphabetically to spot near-duplicates fast. Screaming Frog also flags exact-duplicate content automatically under its "Content" tab, which saves manual comparison work.